

The first thing your brain does when it encounters a person, a brand, an avatar, or a country is run a two-question screen so fast you do not notice you ran it. Are they on my side, or against me? And are they capable of acting on it? A tenth of a second in, before you can name a single fact about who they are, your social-perception system has already plotted them on a two-dimensional grid — warm or cold, competent or incompetent — and pre-loaded the emotion you are about to feel toward them, which is then the thing you reason from rather than about (the affect heuristic). Admiration, pity, envy, or contempt. That is not a figure of speech. Willis and Todorov (2006) showed faces for 100 milliseconds and got trait ratings that correlated highly with the ratings people gave the same faces with no time limit at all; extra exposure time raised confidence and made judgements harsher, but it did not raise the correlations. Worth being precise about what that does and does not show: it is evidence that the judgement is made fast, not that it is right — a 2021 meta-analysis puts the face-level correlation between perceived and measured trustworthiness at about .14. The grid is older than language and faster than reasoning. It is also frequently wrong, and it still determines whether the next interaction goes anywhere worth going.
That grid is the Stereotype Content Model. In 2002 Susan Fiske, Amy Cuddy, Peter Glick and Jun Xu published the cleanest two-axis map of intergroup perception the field has ever produced and showed that across 23 societal groups, rated by U.S. adult and student samples, the same two dimensions accounted for almost everything — including which prejudices stayed warm and which turned violent. Five years later, Cuddy, Fiske and Glick extended it into the BIAS Map (Behaviors from Intergroup Affect and Stereotypes) and pinned each quadrant to a specific behavioral output: who you help, who you cooperate with, who you exclude, and who you attack.
One map is never enough for me, though. Warmth and competence tell you how people judge a group; Realistic Conflict Theory explains why those judgments harden, and the Framing Effect shows how a single sentence can shift them. That is why I keep every framework side by side in my Behavioral Framework Library: the grid you are about to learn gets sharper each time you lay another model over it.
If you build characters, brands, teams, NPCs, or onboarding flows for a living, the Stereotype Content Model is the closest thing the field has to a cheat sheet for what your audience will instantly feel about a face the second it appears. The post you are reading is the long-form version of that cheat sheet — what the model gets right, where it falls apart, and how to actually use it inside the Octalysis Framework without producing the warmth-versus-competence trade-off that has cost careers and crashed brand launches.
Speed Run Notes
- The Stereotype Content Model says all group stereotypes load on two dimensions — Warmth (intent: friend or foe) and Competence (capability: can act on it or not) — producing four quadrants and four predictable emotions.
- Warmth is predicted by perceived competition (cooperative groups are warm, competitive groups are cold). Competence is predicted by perceived status (high-status groups are competent, low-status groups are not). Two structural inputs, one matrix.
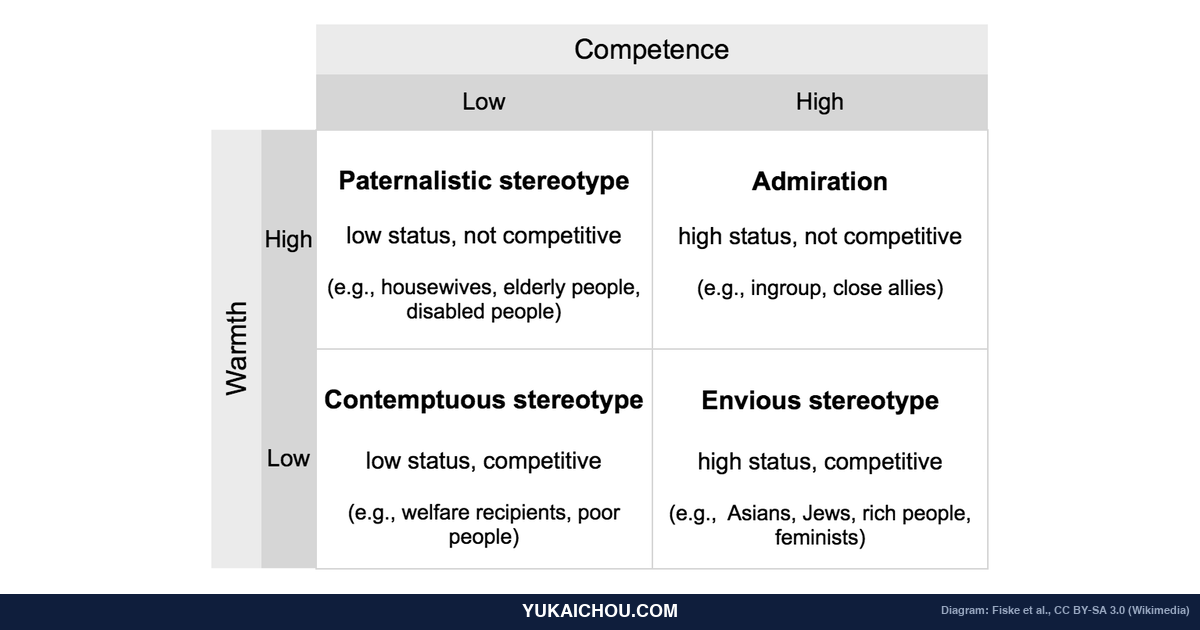
- The four quadrants map to four prejudices: high-high → admiration; high-warmth/low-competence → paternalistic pity; low-warmth/high-competence → envious resentment; low-low → contempt. Most groups land mixed, not extreme.
- The BIAS Map (Cuddy, Fiske, Glick 2007) routes each quadrant to behavior: warmth drives active behaviors (help vs. attack); competence drives passive behaviors (associate vs. ignore). Envy is the conditional quadrant: passive cooperation while the system is stable, hostility when it is not. Contempt, not envy, scored the highest active harm.
- The two dimensions are no longer unchallenged. When researchers stop supplying the axes and let people sort groups freely (Koch et al. 2016; Nicolas, Bai & Fiske 2022), warmth stops behaving like a primary dimension.
- For Octalysis design: every avatar, NPC, brand, and team archetype lives in one of those four quadrants the moment it loads, and the emotion it triggers is set before any later content can re-write it. Load both axes deliberately: a single-axis design lands off-diagonal by default.
- Where it falls apart: morality looks like a separate primary dimension (Brambilla & Leach), the compensation effect distorts side-by-side ratings, and the model captures conscious stereotypes far better than automatic ones.
Table of Contents
- What Is the Stereotype Content Model
- The Core Findings: Warmth, Competence, and the Four Quadrants
- What Fiske, Cuddy, Glick and Xu Got Right
- Where the Stereotype Content Model Falls Apart
- The Brain on Warmth and Competence
- The Stereotype Content Model vs Other Theories
- The Stereotype Content Model in the Real World
- The Elephant in the Room
- How to Apply the Stereotype Content Model with the Octalysis Framework
- Practical Steps to Apply the Stereotype Content Model
- Frequently Asked Questions
Author Credibility: Yu-kai Chou

Yu-kai Chou created the Octalysis Framework after studying gamification since 2003 — years before the term entered mainstream vocabulary. As a Human-Systems Architect & Behavioral Designer, his framework has been applied by LEGO, Microsoft, Porsche, Coca-Cola, Salesforce, and MrBeast, impacting over 1.5 Billion Users.
Chou has taught the Octalysis methodology at Harvard, Stanford, Yale, Tesla, Google, BCG, and IDEO.
His work has been cited by Harvard, Stanford, MIT, Forbes, Wall Street Journal, Wired, US Department of Energy, NIST, NSF, NCBI, US Department of Education, ClinicalTrials.gov, and Google Scholar — with 3,700+ more academic publications. Explore his books here.

Why this model, on this site. The Octalysis Framework is a motivation model: it tells you which of eight Core Drives a design is pulling. It says nothing about who the player thinks they are looking at. The Stereotype Content Model fills that gap, and the gap is where a lot of design work quietly fails — “efficient but cold” brands losing to “friendly and capable” ones at the same price point, villains who feel pitiable landing harder than villains who feel only menacing, a leaderboard design that reads as aspirational to the team and as resentment-bait to everyone below the fold.
The two-axis read below is the part of this literature I reach for most often when a character lineup or a brand voice is not landing and nobody in the room can say why. What follows is the long version: what the model gets right, where the evidence has moved since it was published, and how to run it inside Octalysis without producing the warmth-versus-competence trade-off it is usually used to excuse.
What Is the Stereotype Content Model
The Stereotype Content Model is a social-psychology framework developed by Susan T. Fiske and her collaborators that claims all stereotypes about groups can be efficiently described along two orthogonal dimensions — warmth (whether the group’s intentions toward the perceiver are positive or negative) and competence (whether the group has the capability to act on those intentions). The two dimensions are not arbitrary. They correspond, the authors argue, to the two questions that any social animal needs to answer before deciding whether to approach or avoid another organism: Are they friend or foe? And are they strong enough to matter?
The model emerged from a 2002 paper in the Journal of Personality and Social Psychology, “A Model of (Often Mixed) Stereotype Content: Competence and Warmth Respectively Follow From Perceived Status and Competition,” co-authored by Fiske, Amy Cuddy (then her doctoral student), Peter Glick, and Jun Xu. Across 23 societal groups, rated by both adult and student U.S. samples, ratings on warmth-related and competence-related traits separated cleanly into two factors that were nearly orthogonal. Crucially, most groups did not land at the high-high or low-low corners. They landed in the off-diagonal quadrants — high on one dimension, low on the other — which is why the paper’s subtitle calls the resulting stereotypes “often mixed.”
Two structural antecedents predict where a group lands. Status — how high a group sits in the perceived social hierarchy — predicts perceived competence. Groups with prestige, money, education, or institutional power get rated as competent, regardless of any actual performance data — which is system justification doing its work one inference earlier than the model usually gets credit for. Competition — whether a group is seen as competing with the perceiver’s in-group for finite resources, recognition, or values — predicts perceived warmth, in the negative direction. Cooperative groups feel warm; competitive groups feel cold. The model’s explanatory power comes from collapsing the messy individual-level facts about a thousand groups into two perceptual dimensions driven by two structural inputs — a stereotype in the schema-theory sense, a structure that decides what gets noticed before it decides what gets concluded.
The intellectual lineage is older than the 2002 paper. Solomon Asch, in his 1946 work on impression formation, had already shown that warmth was a “central trait” that reorganized how every other trait about a person was interpreted — the same spillover mechanism the halo effect describes at the level of individual impressions. Rosenberg, Nelson and Vivekananthan (1968) had already split person perception into a “social good–bad” axis and an “intellectual good–bad” axis. Bogdan Wojciszke (1994) had shown the same two-factor structure recurring across European samples. Fiske and her team did not invent the two dimensions; they assembled the case that those dimensions are the structure of stereotype content, mapped each quadrant to a specific emotion, and connected the model to a structural theory of where stereotypes come from. That synthesis is what gave the model the staying power its predecessors lacked.
If you only remember three things from this section, remember these. Warmth and competence are the two dimensions every social perception travels on. Status drives competence; competition drives (low) warmth. Most stereotypes are mixed, not extreme. Everything else in the post is consequence.
The Core Findings: Warmth, Competence, and the Four Quadrants
The cleanest way to read the Stereotype Content Model is as a 2×2. Cross warmth on the vertical axis with competence on the horizontal, and you get four quadrants, each tied to a stable emotional reaction and a stable behavioral tendency.
Quadrant 1 — High Warmth, High Competence: Admiration
This is the in-group quadrant. In the United States samples Fiske and her team ran, people placed their own group, their close allies and their cultural reference groups in the upper-right corner: “middle class,” “Christians,” and “Americans” all clustered here. That part does not travel as cleanly as the rest of the model. The cross-cultural extension (Cuddy et al., 2009) found that collectivist samples did not put their reference groups in the high-high cell — a result worth holding onto if you are designing a hero archetype for a non-U.S. audience and assuming the in-group reads as admirable by default. The associated emotion is admiration with a hint of pride. The behavioral tendency is both active and passive facilitation — you help these people directly when they need help, and you cooperate with them by default the rest of the time.
For a designer the upper-right is where heroes, mentors, customer-favorite brands, and trusted leaders live. It is also a quadrant most products fail to land in, because landing in it requires both dimensions, and any single-axis optimization — for efficiency, or for relatability, or for prestige — pushes the design into one of the off-diagonals.
Quadrant 2 — High Warmth, Low Competence: Pity
This is the paternalistic quadrant. The 2002 paper placed elderly people, disabled people, and (in mid-twentieth-century American stereotypes) housewives here. The emotion is pity or sympathy, and the behavior pattern is active facilitation paired with passive harm. You help them in concrete ways — opening doors, donating, advocating — while simultaneously leaving them out of the rooms where decisions get made. Paternalistic prejudice feels generous to the perceiver and is one of the hardest forms of prejudice to dislodge precisely because the perceiver does not experience it as prejudice at all.
In product and brand design, the pity quadrant is where well-meaning campaigns about “underserved” populations live, where charity-themed gamification often lands, and where customer-service archetypes designed to be “non-threatening” accidentally end up. The retention cost is enormous: users in this quadrant feel the warmth, register the implied incompetence, and quietly leave.
Quadrant 3 — Low Warmth, High Competence: Envy
The envious quadrant is the most explosive corner of the model. Groups perceived as competent but cold — the 2002 paper sampled rich people, Asian Americans, Jewish Americans, and career women — trigger envy and resentment. The behavioral pattern is the most dangerous of any quadrant: passive facilitation under stable conditions, but active harm under threat. You will work with these groups, even rely on them, when the system is stable and the gains are mutual. The moment resources tighten or status feels threatened, the same competence that made them useful makes them targets.
Envy is also where this model meets social comparison theory: an upward comparison the perceiver cannot close is what gives competence-without-warmth its sting. This is the quadrant that produces scapegoating during economic downturns, “model minority” backlash, and the specific kind of violence that targets visibly successful out-groups. Be careful about how strong a claim this quadrant will carry, because the popular version of it is backwards. In Cuddy, Fiske and Glick’s (2007) own data the highest mean active harm belonged to contempt, not envy (M = .556 against .115; admiration and pity sat below the midpoint at −.432 and −.246). The envy-to-active-harm path was the paper’s weakest link: significant only at the individual level of analysis, weak in two of its studies, and fully mediated by anger in the study built to test it. So what makes envy the quadrant to watch is not the size of the harm it predicts. It is the combination — the only quadrant whose two predicted behaviors point in opposite directions, cooperation and attack, with system stress as the switch. The implication for designers is still sharp: a brand or character optimized for competence at the expense of warmth is not sitting on the biggest fault line, it is sitting on the one whose state you cannot read from steady-state metrics.
Quadrant 4 — Low Warmth, Low Competence: Contempt
The lower-left quadrant produces contempt and disgust. The 2002 paper placed homeless people, drug addicts, and (in the American sample) welfare recipients here. The behavioral pattern is passive harm and active harm — exclusion, dehumanization, sometimes physical aggression. Harris and Fiske’s 2006 fMRI work on this quadrant found that low-low targets did not engage the medial prefrontal cortex the way other social targets did — the region that reliably comes online when a perceiver is thinking about a person at all. That gap, not an absolute silence, is what the authors read as dehumanization.
For designers, this quadrant is the one to never end up in. No legitimate consumer brand wants to live here, no protagonist works here, no NPC class wants to read like the contempt quadrant unless contempt is the design goal — which, in moderation, it sometimes is, for villains and disposable enemy mobs in games. Even there, the dehumanization risk means contempt-grade design choices need to be deliberate.
The BIAS Map: From Stereotype to Behavior
The 2002 paper stopped at affect. The 2007 follow-up — Cuddy, Fiske and Glick’s “The BIAS Map: Behaviors from Intergroup Affect and Stereotypes” in the Journal of Personality and Social Psychology — extended the model into behavior, and the result is the operational version of the framework.
The BIAS Map proposes that each of the four quadrants drives two distinct kinds of behavior. Warmth drives active behaviors: high warmth produces active facilitation (help, defend, advocate); low warmth produces active harm (attack, sabotage, denigrate). Competence drives passive behaviors: high competence produces passive facilitation (associate with, cooperate with, defer to); low competence produces passive harm (ignore, exclude, neglect). The active-passive split matters because it explains why some prejudices look quiet (passive harm) while others look loud (active harm), and why a single quadrant can produce both kinds of behavior in the same person depending on the situation.
The model also explains a peculiar empirical finding the simple 2×2 cannot: in the envy quadrant, behaviors flip. Passive facilitation predominates in normal conditions (you cooperate with high-competence-low-warmth groups because their capability is useful), but a sudden destabilization — recession, terror attack, election upset — flips the same group from cooperator to scapegoat overnight, with active-harm behaviors spiking. This is the BIAS Map’s most important contribution to design: it tells you which quadrant configurations are stable and which are conditional. Admiration is stable. Pity is stable. Contempt is stable. Envy is conditional, and the condition is system stress.
What Fiske, Cuddy, Glick and Xu Got Right
Strip the Stereotype Content Model down to its three load-bearing claims and ask which ones have survived more than two decades of replication, methodological scrutiny, and cross-cultural extension. Three claims are intact, and they are the three that matter for design.
The two-dimensional structure travels, and it has been tested at scale. Cuddy, Fiske, Kwan, Glick, Demoulin and an international team ran the model across eight European and three East Asian samples (Cuddy et al., 2009). The two-factor warmth-competence structure recovered in each, and the structural antecedents — competition predicting (low) warmth, status predicting competence — held with culturally specific variation rather than structural reversal. The scale went up sharply eight years later: Durante and colleagues (2017) pooled 49 samples from 38 nations (n = 4,344) and found that higher national income inequality predicts more ambivalent — i.e. more off-diagonal — stereotype clusters, with a curvilinear twist worth knowing: both very peaceful and very conflict-ridden nations show unambivalent us-them patterns, while the middle of that range is where ambivalence peaks. That is a structural prediction being tested against national-level data and surviving, which is a harder bar than “peer-reviewed and published.”
Mixed stereotypes — the off-diagonal quadrants — are the empirically dominant case. This was the finding the 2002 paper went out of its way to highlight, and it has held up. When researchers run modern SCM batteries, the median group lands somewhere off the high-high to low-low diagonal. That has implications a designer can use immediately: the question to ask about your character or brand is not “is this entity positively or negatively perceived?” but “which off-diagonal quadrant does the audience read it into, and what behavior does that quadrant license?” A “positive” brand that lives in the pity quadrant and a “positive” brand that lives in the admiration quadrant are not interchangeable. They will produce different actions even though both score above the midpoint on overall favorability.
The active-passive behavioral split (the BIAS Map’s contribution) gives the model behavioral teeth that its predecessors lacked. The Asch and Rosenberg lineage was a perception model. Fiske and her co-authors turned it into a perception-emotion-behavior chain by routing each quadrant through a specific affect and into a specific behavior class. That is what makes the model usable for design rather than just descriptive social science. When your character lands in the envy quadrant, you do not just know “people will feel envy.” You know the model predicts cooperation under stable conditions (passive facilitation) and hostility under stress (active harm) — and, per the 2007 data, that the second half of that prediction is the weaker one, carried by anger rather than by envy directly. That is still more than a feeling to design around: it tells you which conditional path to stress-test, and which emotion to watch for if you want early warning.
One quieter contribution is doing more work in the design world than people realize, and it needs a caveat the design world usually drops. Fiske and her team framed warmth and competence as separable — two factors, not one bipolar scale — which implies a design space where you can buff the warmth of a competent-cold brand without paying for it in competence.
The caveat: separable is not the same as independent, and the evidence has firmed up on exactly this point. Imhoff and Koch (2017) report that the relation between the two is curvilinear rather than flat, and generalise it from U.S. and German group ratings to more than 30 group samples from more than 20 countries. Near the middle of the space the two move fairly freely; out at the extremes they trade against each other, which is the same wall the compensation effect below describes from the ratings side. So the usable version of the claim is narrower than “two sliders” and still worth having: you have real room to move on one axis without losing the other, and that room shrinks the further out you already are. A brand at the far competence edge has to buy warmth against resistance. A brand in the middle mostly does not. Most designs that ended up off-diagonal got there by treating the two as one slider and never testing whether they had room.
Where the Stereotype Content Model Falls Apart
Four failure modes are worth a designer’s attention because each one changes how the model should be applied, not whether it should be. The model is a useful map; these are the places where the map and the territory diverge. The fourth is the most serious and the least discussed outside the journals, so it goes last rather than first.
Morality may be a separate primary dimension, not a sub-component of warmth
The most serious challenge to the two-dimensional structure comes from a research program led by Marco Brambilla, Colin Wayne Leach, Bogdan Wojciszke and their collaborators. Their argument, sustained across more than a decade of papers (Brambilla, Rusconi, Sacchi & Cherubini 2011; Leach, Ellemers & Barreto 2007; Brambilla & Leach 2014), is that warmth in the original SCM conflates two distinct sub-dimensions — sociability (how friendly and approachable a group is) and morality (how trustworthy and principled it is) — and that morality, not sociability, is the dimension that does the actual heavy lifting in stereotype formation.
The empirical pattern is consistent. When research participants form impressions of groups or persons, morality information is processed faster than sociability information, weighted more heavily in the final judgment, and produces stronger behavioral effects. A group can be friendly but untrustworthy; the friendliness will not save it from negative downstream behavior. A group can be unfriendly but principled; the principledness will pull positive cooperation despite the social friction. The original SCM’s warmth dimension does not separate these cases, and the resulting predictions in domains like brand trust and political messaging are noticeably less precise than a three-dimensional Sociability-Morality-Competence model produces.
For a designer, the implication is concrete. If you have applied the SCM to your brand or character archetype and the predictions feel directionally correct but quantitatively off, the most likely diagnosis is that the warmth axis is hiding a morality-sociability split. Audit your warmth signals. Does your brand voice cue principledness, or only friendliness? Does your villain’s coldness signal corruption, or only social distance? The 2×2 will let you build something that scores fine; the 3-axis upgrade will let you build something that lands.
The compensation effect distorts ratings under direct comparison
Nicolas Kervyn, Vincent Yzerbyt, and colleagues (Kervyn, Yzerbyt, Demoulin & Judd 2008; Yzerbyt, Provost & Corneille 2005) have documented a robust compensation effect: when two groups are evaluated side by side, raters systematically push the warmth-competence ratings in opposite directions, even when the underlying information would justify high-high or low-low ratings. If Group A is rated as more competent than Group B, raters will rate Group B as warmer than Group A, regardless of whether the warmth information actually supports that.
The mechanism appears to be a soft justice motive — the same machinery the just-world hypothesis describes: the perceiver wants the world to be fair, and a high-high group offends that motive by “winning” on both dimensions, so ratings get re-balanced to produce a more equitable distribution of perceived virtue. The compensation effect is a serious problem for any application of the model that relies on comparative ratings, including brand-perception tracking, political-candidate evaluations, and any A/B test that runs two characters against each other in a within-subjects design. The numbers you get back will not reflect absolute perception; they will reflect the comparison-induced compensation, and the design decision based on those numbers will be wrong.
The practical fix is to run between-subjects evaluations whenever possible, treat any within-subjects warmth-competence rating as a relative not absolute measurement, and accept that the “land in the high-high quadrant” design goal may be harder to achieve than the model implies, because the audience’s mind is doing background compensation work that pulls every successful design back toward the diagonal.
Implicit and explicit stereotypes diverge, and SCM mostly captures the explicit
The SCM as originally validated relies on explicit, self-reported ratings of how warm and competent each group is. Anything explicit is subject to social-desirability pressure, demand characteristics, and the general well-documented gap between what people say about groups and what they implicitly associate. The Implicit Association Test literature, as well as more recent affective-priming and reaction-time methods, repeatedly find that participants who rate a group as warm-and-competent on an SCM scale produce automatic associations that load on a different (often more negative) part of the warmth-competence space.
The implicit-explicit divergence does not invalidate the model. It does mean that an SCM-based design optimization will work for the part of the audience’s response that is conscious, deliberate, and survey-reportable, and will not necessarily work for the parts that drive split-second avoidance, micro-aggressions, or implicit hiring biases. Designers building for the deliberate part of the funnel — brand perception, character archetype, customer-service tone — are mostly fine. Designers building for the automatic part — first-impression NPC encounters, sub-second avatar reactions, system-1 customer-service triage — need to pair SCM with implicit-measure validation, because the explicit-only ratings will mislead them.
When researchers stop supplying the axes, warmth stops behaving like a primary dimension
This is the challenge that would change the most if it holds, and it is the one almost never mentioned in applied write-ups of the model. Every classic SCM study hands participants the dimensions: here are some groups, now rate each one on warmth-related and competence-related traits. That design can confirm that the two dimensions organise the ratings. It cannot tell you whether those are the dimensions people would have used on their own.
Koch and colleagues (2016) took the axes away. Across seven experiments with 4,451 participants, people chose which groups to consider and judged how similar groups were to each other, with no dimensions supplied. Two dimensions came out of the similarity space: agency / socioeconomic success, which maps closely onto competence, and conservative–progressive beliefs, which has no counterpart in the Stereotype Content Model at all. Communion — the family warmth belongs to — did not emerge as a dimension. It appeared instead as a property of position within that two-dimensional space, roughly, how central or average a group sits. Their label for the result is the ABC model.
The follow-up work pushed the same way. Imhoff and Koch (2017), cited above for the curvilinear relation, generalised that non-independence across 30-plus group samples from 20-plus countries. And Nicolas, Bai and Fiske (2022) — Fiske herself among the authors — built a taxonomy from what people say about groups in open-ended responses rather than on scales, and found a content space considerably wider than two dimensions, with sociability and morality sitting separately in it, as the morality critique above would predict.
None of this means the 2×2 is wrong, and it is worth being exact about what is in dispute. Warmth and competence remain the dimensions that organise ratings and that predict the four emotions, which is most of what a designer uses the model for. What is contested is whether warmth is primary — a dimension perceivers reach for unprompted — or whether it is something that falls out of a different underlying structure. For design work, two consequences are concrete. First, if you run the Step 2 audience plot below using warmth and competence scales, you are doing the thing the critique is about, and you should expect the output to be organised, confident, and possibly not the axis your audience was actually using. Open-ended “describe this character in your own words” passes are the cheap corrective. Second, the dimension Koch’s method surfaced that the SCM has no slot for — beliefs — is one your audience may well be reading off a brand or a character, and the two-axis map will never show it to you.
The Brain on Warmth and Competence
The neuroscience of the Stereotype Content Model is unusually consistent for a social-psychology framework. Three converging findings make the case that warmth and competence are not just convenient survey factors but separable cognitive operations with distinct neural signatures.
The first finding, from Lasana Harris and Susan Fiske (2006, Psychological Science), concerns the medial prefrontal cortex — the region that reliably comes online when a perceiver is thinking about another person at all. Photographs of low-low targets, the groups the model places in the contempt quadrant, did not engage mPFC the way the other social targets in the same study did, and participants reported disgust rather than any sense of shared humanity. The authors read that gap as dehumanization: the brain handling these targets less like people and more like objects. Note what the finding is and is not — a differential response relative to other social targets, which is the comparison that makes it meaningful, rather than a flat absence of activity.
It is also not a closed question. Later work has catalogued conceptual problems in psychological models of dehumanization generally, and has asked whether a stereotype-content account can cover historical cases — Nazi antisemitism being the usual example — where the targeted group was stereotyped as highly competent rather than as incompetent. Hold the finding at the strength it was measured: a robust result about one corner of the map, not a general theory of how atrocity happens.
The second finding is about schadenfreude, and it is worth separating the two studies usually blurred together here, because they measured different things.
Cikara, Botvinick and Fiske (2011) scanned Red Sox and Yankees fans watching schematic baseball plays. Positive outcomes — their team succeeding, or the rival failing, even against a third team the fan had no stake in — activated the ventral striatum, the reward structure; negative outcomes activated anterior cingulate and insula. The result that matters is the link outward: fans with more striatal response to rival failure reported greater willingness to aggress against rival fans two weeks later. That is a rivalry study, not a stereotype-content study, and it says nothing directly about the four quadrants.
The quadrant-level evidence comes from Cikara and Fiske’s “Bounded Empathy” work (2011, Journal of Cognitive Neuroscience), which did manipulate target type across the model’s cells. Its headline region is the insula rather than the ventral striatum, and one of its results cuts against the intuition a designer brings to this material: participants felt least bad about misfortunes befalling envied targets — and were least willing to endorse harming pitied ones, despite pitied targets being out-group members too. Insula response to negative events ran lowest for disgust targets, then envy, then pride, and highest for pity.
Put the two together and the honest reading is narrower than “the brain rewards us for the envied group’s setbacks, which is how scapegoating consolidates.” It is this: pleasure at a rival’s failure is real, measurable, and predicts willingness to harm — and the group a perceiver protects least is not the one they feel most hostile toward, but the one whose suffering registers least.
The third line of evidence does not come from imaging at all, and it is the one most often overstated. Oosterhof and Todorov (2008) ran a principal-components analysis on trait judgements of emotionally neutral faces and recovered two orthogonal dimensions, which they named valence (well approximated by trustworthiness) and dominance. Those are not warmth and competence, and the study measured neither the speed of extraction nor any neural dissociation — claims you will see attached to it anyway.
What it actually reports is a better argument for this page than the misattribution was. Valence tracks features resembling expressions that signal whether a person should be approached or avoided; dominance tracks features signalling physical strength or weakness; and the authors read the whole system as an overgeneralisation of mechanisms for inferring harmful intentions and the ability to cause harm. Intent and capability — arrived at from pixels rather than from group ratings, and landing on the same two questions the Stereotype Content Model says every social judgement runs. A 41-country replication in 2021 found the valence-dominance structure generalises well across regions when the dimensions are forced to be orthogonal, and considerably less well when correlated solutions are allowed — the same caveat the compensation and curvilinearity results raise one level up. Two dimensions, two methods, one honest qualifier: the structure is robust, its orthogonality is an analytic choice as much as a finding.
Put together, the evidence supports a moderate version of the model rather than the strong one. Warmth and competence are not arbitrary survey descriptors: the contempt corner has a replicable neural signature, pleasure at a rival’s misfortune predicts willingness to harm, and a bottom-up model of face evaluation independently lands on intent and capability. What the evidence does not establish is that the four quadrants are four distinct processing modes, or that the BIAS Map’s conditional path has a reward signature of its own. Designers can treat the two axes as real machinery. The quadrant boundaries are still a convenient way to talk about that machinery, not a thing the brain has been shown to draw.
The Stereotype Content Model vs Other Theories
The SCM does not stand alone. Three neighboring frameworks describe overlapping territory, and knowing where they diverge is the difference between using SCM as a precision tool and using it as a generic excuse.
The closest neighbor is the Big Two tradition associated with Andrea Abele and Bogdan Wojciszke (2007 and onward), which argues that all of person and group perception loads on two superordinate dimensions called communion (other-orientation, including warmth and morality) and agency (self-orientation, including competence and assertiveness). The Big Two is functionally identical to SCM at the descriptive level but differs in two ways: communion explicitly includes morality (which SCM’s warmth conflates), and agency includes a wider range of self-promotional traits than SCM’s competence does. If you are working in the perception of individuals rather than groups, the Big Two is a better fit. If you are working in the perception of groups, SCM’s structural-antecedents account (status → competence, competition → warmth) does work the Big Two does not.
The next neighbor is Social Identity Theory (Tajfel & Turner 1979), which says that mere categorization into groups — even arbitrary categorization — is sufficient to produce in-group favoritism. SIT and SCM are usually treated as complementary. SIT explains the always-on baseline of in-group preference; SCM explains how that baseline differentiates across specific out-groups, with some out-groups landing in the admiration quadrant and others in contempt. Designers building team mechanics should know both. SIT tells you that any boundary will produce some preference; SCM tells you which kinds of boundaries produce which kinds of preference, and which configurations are stable versus volatile.
Realistic Conflict Theory (Sherif et al. 1961) is the third neighbor and the upstream source of one of SCM’s structural antecedents. Sherif’s claim that intergroup hostility comes from competition over scarce resources is exactly the “competition predicts low warmth” pathway in SCM. The relationship is hierarchical: RCT supplies the macro-structural input; SCM converts it into a perceptual map; the BIAS Map converts the perceptual map into specific behaviors. Designers who run a system where players or factions can compete for finite resources should expect the SCM warmth axis to drift downward for the out-group — not as a model failure, but as exactly what SCM predicts when RCT’s precondition is met.
The fourth neighbor, often forgotten, is Implicit Personality Theory in the Asch (1946) and Rosenberg, Nelson & Vivekananthan (1968) lineage. SCM is the group-level extension of these person-perception findings, and the two-factor structure recovered in those individual-target studies is not an accident; it is the same machinery firing at a different unit of analysis. For brand and character design, the implication is that the line between “person perception” and “group perception” is fuzzier than the SCM literature sometimes implies, and a single character can pull either set of associations depending on whether the audience reads it as an individual or as a representative of a category.
The Stereotype Content Model in the Real World
Four domains have generated enough applied SCM work that the practical implications are no longer theoretical. Each one is also a domain where Octalysis designers commonly ship.
Brand strategy and the warmth-competence trade-off
The most heavily applied SCM paper outside the prejudice literature is Jennifer Aaker, Kathleen Vohs and Cassie Mogilner’s 2010 Journal of Consumer Research article, “Nonprofits Are Seen as Warm and For-Profits as Competent: Firm Stereotypes Matter.” The argument is exact: consumer brands are routinely sorted into the same four quadrants the SCM predicts, with measurable consequences for purchase intent, willingness to pay, and trust. Nonprofits typically cluster in the high-warmth-low-competence quadrant; for-profits cluster in the high-competence-low-warmth one. The off-diagonal placement is what produces the behavioral patterns each sector is known for: charitable donations track the warmth quadrant; market-share dominance tracks the competence quadrant. What the paper does not report, and what you should not repeat, is a measured loyalty advantage for brands in the admiration quadrant. Its actual finding is sharper and more awkward for the warm sector: being seen as warm did not sell, because perceived competence was what drove willingness to buy, and the nonprofit quadrant placement cost them exactly there.
The applied takeaway has been picked up by every consultancy with a brand-strategy practice. A premium brand that scores high on competence and is leaking on warmth is not at risk of losing market share to a more competent competitor. It is at risk of losing it to a brand with comparable competence and significantly higher warmth, because the warmth difference resolves the off-diagonal placement that was leaving a behavioral gap on the table. You can see the shape of this in how enterprise and premium brands behave — founder-as-character storytelling, public credit to customers, a softer voice bolted onto an unchanged spec sheet — and it is tempting to narrate specific companies as SCM case studies. I am going to decline the temptation, because nobody outside those companies has the perception tracking to say whether a given warmth campaign moved the warmth rating, held the competence rating, or did neither. Treat the mechanism as the claim: if your competence rating is strong and your warmth rating is leaking, the model says the threat is a comparably competent and noticeably warmer rival, and the remedy is warmth signal that does not read as a competence concession. Whether any particular brand pulled that off is a measurement question, and the measurement is usually private.
Workplace and the role-congruity penalty for competent women
The second domain is hiring, performance review, and workplace evaluation, and it is where getting the direction of the trade right matters most, because the version of this finding that circulates is backwards.
Cuddy, Fiske and Glick (2004) — the paper titled “When professionals become mothers, warmth doesn’t cut the ice” — did not find that competent women get penalised on warmth. It found the reverse exchange: when a working woman becomes a mother, her perceived competence drops and her perceived warmth rises. Working fathers make no such trade; they gain warmth and keep their competence ratings. Participants then reported less interest in hiring, promoting and educating the working mothers — and it was the competence ratings that predicted those decisions. That is the whole argument in the title: the warmth she gains buys her nothing, and the competence she loses costs her the job. The sample was 122 students rating vignettes, so read it as evidence about perception rather than about real hiring outcomes.
The other direction of travel — a competent, assertive woman taking a warmth hit — is also real and also consequential, but it belongs to the backlash and role-congruity literature rather than to this paper. Alice Eagly and Steven Karau’s Role Congruity Theory (2002, Psychological Review) supplies the mechanism: prejudice arises where the perceived attributes of a group and the perceived requirements of a role are mismatched, which is why the same assertive behavior reads as leadership in one person and as coldness in another. Two different penalties, two different literatures, and keeping them apart is what lets an organisation design against the right one. Both have a counterpart on the receiving end, which is stereotype threat: this model describes what the perceiver does, not what being perceived that way costs the person on the other side of it.
The applied stakes are concrete, and the design implication follows the measurement rather than the slogan. If competence perception is what moves hiring, promotion and development decisions, then an evaluation system that leans on warmth-flavoured language — “a pleasure to work with,” “great team player” — is not being kind, it is quietly routing a candidate away from the axis the decision actually runs on. The structural fixes are the ones that survive this: criteria defined before the candidate is in the room, competence evidence recorded as specifics rather than impressions, mentorship matched structurally rather than by who feels approachable, and — from the morality critique above — warmth signals that carry principledness and not only friendliness, since those are the ones that pull cooperation. None of that requires naming the model. It does require knowing which axis the decision is standing on.
Political and intergroup messaging
The third domain is political and intergroup communication, and here the model’s most useful contribution is its causal ordering rather than any particular campaign result. The 2002 paper’s structural claim is that warmth is downstream of perceived competition and competence is downstream of perceived status — which is why intergroup contact works best under cooperative, equal-status conditions and can backfire without them. Durante and colleagues’ 38-nation data is consistent with that ordering operating at the level of whole societies: the structural condition (inequality, position on the peace-conflict range) tracks the shape of the stereotype content, rather than the other way round. Susan Fiske’s Envy Up, Scorn Down (2011, Russell Sage Foundation) is the long-form version of the status half of that argument.
The honest caveat is that I am not aware of a clean head-to-head experiment showing that competition-reframing messages beat warmth-asserting messages, and this post previously implied there was one. If you need that comparison for a real campaign decision, run it yourself on your own audience; the model tells you which lever is theoretically upstream, not how much it moves.
For brand and product messaging the transfer is a hypothesis worth testing rather than a result to bank. If warmth really is downstream of perceived competition, then a campaign that restructures the competition framing — showing the audience your brand cooperating with their goals rather than extracting from them — should outlast a campaign that simply asserts the brand is friendly. Changing the antecedent is the more durable move if the ordering holds. Build the test so you find out which.
NPC, avatar, and character design in games
The fourth domain is character design, and the SCM provides one of the cleanest design tools the field has. Every NPC, every party member, every brand mascot, every voice-assistant persona lands in one of the four quadrants the moment its face appears, and the player’s behavior toward it is largely set by quadrant before any later content can re-write it. Companion characters land in admiration. Disposable mob enemies land in contempt. Aristocratic antagonists and rival mages land in envy. Comic-relief characters and broken-down old mentors land in pity.
The studios that get character lineups right tend to be the ones who think about the quadrant distribution explicitly — making sure the cast covers the four quadrants in proportions that match the emotional palette of the game. The studios that get it wrong tend to be the ones who optimize every character for the same single dimension (usually competence) and end up with a cast where every face triggers the same reaction. The Octalysis section below turns this into a concrete worksheet.
The Elephant in the Room
The Stereotype Content Model was developed inside the prejudice and intergroup-relations literature, by researchers studying actual stereotypes about actual social groups, with all of the political and ethical weight that work carries. Applying it to brand strategy and character design is an extension the literature itself made — the consumer-behavior work above is co-authored by people inside that tradition — but the extension carries a responsibility most applied uses do not acknowledge.
The responsibility is this: the same model that lets you design a more admired brand also lets you design a more contemptible out-group. The same compensation effect that explains why competent women get penalized on warmth also lets a marketing team strategically place a competitor in the envy quadrant where it becomes a target for active harm. The neural finding that contempt-quadrant targets are processed less like people and more like objects is not a designer’s tool to weaponize — and the moral-disengagement literature is the record of what people do once that processing is in place. It is a warning that certain design choices — a faceless enemy mob, a dehumanizing competitor framing, a low-warmth-low-competence customer archetype baked into a service script — have measurable cognitive consequences for the audience.
The elephant in the room of any SCM-informed design work is that the framework is morally agnostic, but its applications are not. Designers who use the model to land their own brand or character in the admiration quadrant are doing what the model was extended to enable. Designers who use it to push another group into contempt are running the prejudice machinery the model was built to study, with the model’s predictive power on their side. The line between those uses is not always crisp, especially in competitive brand work, and a working ethics sense for the framework is part of what separates designers who use it well from designers who use it cynically.
None of this is a reason to avoid the model. It is a reason to use it with the same care a structural engineer uses load calculations: knowing the math is what lets you build buildings that stand up, and knowing the math also means you are responsible for buildings that fall down because you specified the wrong materials. SCM is structural math for social perception. Design accordingly.
How to Apply the Stereotype Content Model with the Octalysis Framework
The Stereotype Content Model is a perception model. The Octalysis Framework is a motivation model. Putting them together is a one-step move: the four SCM quadrants map onto specific Octalysis Core Drives, and once you know the mapping, every character, brand, and team archetype in your design becomes a Core Drive lever.

The mapping is dense, so the bullet sketch first, then the design implications.
- Admiration quadrant (high warmth, high competence) → Core Drive 1 (Epic Meaning & Calling) and Core Drive 5 (Social Influence & Relatedness). Admiration-quadrant entities feel like part of the player’s side in a story bigger than either of them and like reliable allies in the social mesh. The associated Game Techniques are Mentorship (#61) and Social Treasure (Gifting, #63), with Core Drive 1’s higher-meaning framing doing the rest of the work.
- Pity quadrant (high warmth, low competence) → Core Drive 5 (Social Influence) with a Black-Hat tilt toward Core Drive 8 (Loss & Avoidance). Pity-quadrant entities pull caretaking behavior, but the implied incompetence routes through Core Drive 8 (Loss & Avoidance) as “don’t let them down.” Game Techniques: Mentorship (#61) inverted so the player is the mentor, plus protective escort and caretaking loops and sympathy-driven mission framing.
- Envy quadrant (low warmth, high competence) → Core Drive 6 (Scarcity & Impatience) and Core Drive 4 (Ownership & Possession). Envy is the Octalysis Black-Hat reading of competence-without-warmth: the entity has what the player wants and is unwilling to share. Game Techniques: Anchored Juxtaposition (#69) with rivals one tier above, Magnetic Caps (#68) on aspirational rewards, and status displays calibrated to sit slightly out of reach.
- Contempt quadrant (low warmth, low competence) → Core Drive 8 (Loss & Avoidance) and Core Drive 7 (Unpredictability & Curiosity). Contempt-quadrant entities are disposable threats and obstacles, pulling avoidance and clearance behavior. Game Techniques: trash-mob design, Sudden Rewards (Easter Eggs, #30) on clearance, and any “clean up the mess” loop.
Three concrete design moves drop out of the mapping.
Move 1: Build a quadrant audit into your character lineup. List every named character, brand persona, NPC class, and faction in your design. Assign each one a quadrant on a single 2×2. Look at the distribution. If 80% of your cast lives in the admiration quadrant, your design is emotionally flat — everything pulls the same warm-competent reaction, and the player’s emotional palette never opens past mild approval. If 80% lives in contempt, you have built a target-rich shooting gallery with no emotional ladder. I am not going to hand you a target ratio, because the right distribution is a function of the emotional arc you are building and nobody has published a benchmark worth quoting. What the audit is for is the shape of the distribution: a cast that occupies one corner can only produce one feeling, and a corner left empty is an emotion your story cannot reach for when it needs it.
Move 2: Use the BIAS Map to predict and design behavioral tendencies, not just feelings. A character that lives in the envy quadrant is a passive-cooperation-under-stable-conditions entity who will become an active-harm target the moment the system stresses. If your design’s late-game beats include resource scarcity, faction wars, or status threats, the envy-quadrant characters are the ones who will absorb the players’ aggression. That is sometimes the design intent (rival mage who deserves to be brought down). It is sometimes a disaster (a competent-but-cold player class that becomes the target of in-game harassment the moment the meta shifts). Plan the conditional path the BIAS Map predicts, not just the steady state.
Move 3: Treat warmth and competence as two independent sliders for any brand, character, or team archetype. The single most common SCM-informed design mistake is treating the two dimensions as a trade-off when the model says they are orthogonal. A character can become more warm without becoming less competent; a brand can become more competent without becoming less warm. Audit your design copy, your art direction, and your interaction patterns for places where you have implicitly assumed the trade-off and built only on one axis. The fix is usually small — a softer onboarding line, a more confident competence cue in a previously self-deprecating character — and the quadrant shift is reliably the difference between admiration-quadrant performance and off-diagonal performance.
Practical Steps to Apply the Stereotype Content Model
If you want to ship a design that uses SCM rather than just acknowledges it, the next ten paragraphs are the working version of the protocol. Run it on whatever surface you are designing — a single character, a brand, a team mechanic, a customer-service script, an entire NPC roster — and the model becomes a live input rather than a wall decoration.
Step 1: List every entity that the audience will perceive as a person, persona, or group. This includes obvious cases (named characters, brand mascots, customer-service AI personas) and less obvious cases (player-class archetypes, faction names, generic NPC classes, the “voice” of a notification system, the implied protagonist of a marketing campaign). Anything the audience anthropomorphizes lands somewhere on the warmth-competence map and should be on this list.
Step 2: Plot each entity on the 2×2 using audience inputs, not your own. Run a small qualitative pass — five users, fifteen minutes each, “rate this entity on warmth from 1 to 7 and on competence from 1 to 7” — and use the average placement, not your team’s intent. Designer-side ratings systematically diverge from audience ratings, especially in the warmth dimension, and most of the surprises come from the audience reading a competence-coded character as colder than the team intended.
Step 3: Run a quadrant-distribution diagnosis. Look at the four-quadrant map. Identify clusters and gaps. A cast or portfolio with a heavy concentration in one quadrant is rendering an emotionally flat experience. A gap in one quadrant means the corresponding emotion (admiration, pity, envy, contempt) is unavailable to the audience and any narrative beat that needed it will fall short. Decide which quadrants you want at which densities given the genre and emotional arc.
Step 4: Identify any compensation-effect risks. If two adjacent entities in the player’s experience differ on one dimension, expect the audience to compensate on the other dimension whether your content supports it or not. A high-competence rival placed next to an in-group ally will get warmth-compressed; a high-warmth helper placed next to a hero will get competence-compressed. Either lean into the compensation (the rival is supposed to feel cold) or deliberately load both dimensions with strong cues to override it.
Step 5: Audit the warmth axis for sociability vs. morality. For any entity that feels warm but is not landing the way you wanted, check whether the warmth signals are sociability-only (smiles, friendly voice lines, approachable poses) or whether they include morality signals (principled choices, trustworthy commitments, ethical consistency). Brambilla and Leach’s research suggests morality is the heavier of the two warmth sub-dimensions, and a sociability-only warmth will not produce the behavioral facilitation the model predicts.
Step 6: Plan the BIAS Map behavioral path for each quadrant. Admiration produces active and passive facilitation. Pity produces active facilitation and passive harm. Envy produces passive facilitation under steady state and active harm under stress. Contempt produces passive harm and (under threat) active harm. Map your design’s expected player-behavior outputs to these predictions; if the prediction does not match the desired behavior, the quadrant placement is wrong, not the prediction.
Step 7: Stress-test envy-quadrant entities specifically. Envy is the most volatile quadrant. Walk through your design’s late-game, post-launch-meta, and worst-case-scarcity states and ask: which envy-quadrant entity is going to absorb the active-harm pivot? Is the design ready for that? In multiplayer or community contexts, the answer is sometimes “move that entity out of the envy quadrant by adding warmth signals.”
Step 8: Build a warmth-and-competence dual-buff for the entities you want in the admiration quadrant. Admiration is the rarest quadrant and the highest-payoff. The dual-buff means both signals have to be loaded repeatedly across the audience’s touchpoints — one competence cue followed by one warmth cue is not enough, because a quadrant placement is an impression formed from accumulated signal, not a claim you can assert once. Two things make this harder than it sounds, and both come from earlier in this post: the compensation effect is actively pulling your ratings back toward the diagonal while you work, and the room you have to move on one axis without paying on the other shrinks the further out you already sit. Plan for repetition and for resistance, and measure placement rather than assuming it.
Step 9: Re-test after every major design change. Quadrant placement is not stable across narrative beats, season changes, or feature launches. A friendly NPC who suddenly becomes a quest-giver tied to a high-stakes failure mode can shift from admiration to pity in a single update. Re-running the Step 2 audience plot after every major change catches the drift before it ships.
Step 10: Document the quadrant intent in your design spec. The expensive version of this mistake is quadrant drift across team handoffs — a writer intends an envy-quadrant rival, an artist designs the rival in the contempt quadrant, a localization team softens the dialogue into pity, and the shipped character lands in a fourth quadrant nobody intended. A line in the design spec that says “warmth target: low. competence target: high. quadrant: envy. emotional payload: aspirational rivalry” is what keeps that drift from happening. The line costs five seconds. Skipping it costs a re-launch.
Closing Thoughts
The Stereotype Content Model earns the “use this” status I reserve for a short list of frameworks, and it earns it on a narrower claim than its popular version makes. The two dimensions organise group ratings across cultures and at national scale. The four quadrants predict four emotions reliably enough to design against, with one corner — contempt — carrying a replicable neural signature. The BIAS Map turns the perceptual map into behavioral predictions, one of which is strong and one of which is conditional and weaker than it is usually quoted as being. And the structural antecedents — status drives competence, competition drives (low) warmth — tell you not just where you are but which lever is upstream.
What it does not earn: primacy. When researchers stop supplying the axes, warmth stops showing up as a dimension people reach for on their own, and a dimension the model has no slot for — beliefs — does. A map can be the best one available and still not be the territory.
It is also a model that demands honest application. The same machinery that builds admiration-quadrant brands runs the prejudice processes the framework was designed to study, and the line between persuasive design and manipulative design runs straight through the four-quadrant map. The morality dimension that Brambilla and Leach have been pushing for is not just a refinement of the model. It is a reminder that the perceived warmth of any entity carries an ethical signal, and that designs which load warmth without backing it with morality cues are running the same play that lands politicians and brands in trouble when the cover gets pulled.
If you take one thing from this guide, take the separability claim in its honest form. Warmth and competence are not one slider — but they are not two fully independent ones either. You have real room to move on one without losing the other, and that room narrows the further out on either axis you already are. Most teams ship designs that implicitly chose one axis and let the other drift, then conclude the trade-off was inherent. It usually was not; they just never tested where their room ran out. The teams that land in the admiration quadrant load both signals deliberately, audit for the compensation effect that drags ratings back toward the diagonal, and run the work as a structural problem rather than a tone problem. The Stereotype Content Model is the structural map. Use it.
If you want the worked-example version of this protocol — with a quadrant-audit worksheet, real studio before-and-afters, and the dual-buff campaign template — that is what Actionable Gamification walks through chapter by chapter.
Frequently Asked Questions
What is the Stereotype Content Model in simple terms?
The Stereotype Content Model is a social-psychology framework which claims that all stereotypes about groups of people can be efficiently described along two dimensions — warmth (whether the group’s intentions toward the perceiver are good or bad) and competence (whether the group has the capability to act on those intentions). Combining the two dimensions produces a 2×2 matrix with four quadrants, and each quadrant is associated with a distinct emotional reaction (admiration, pity, envy, or contempt) and a distinct behavioral pattern. The model was developed by Susan Fiske, Amy Cuddy, Peter Glick, and Jun Xu in 2002.
Who developed the Stereotype Content Model?
The model was introduced in a 2002 Journal of Personality and Social Psychology paper titled “A Model of (Often Mixed) Stereotype Content: Competence and Warmth Respectively Follow From Perceived Status and Competition,” co-authored by Susan T. Fiske of Princeton University, Amy J. C. Cuddy (then a doctoral student at Princeton, later at Harvard Business School), Peter Glick of Lawrence University, and Jun Xu. Fiske had been working on the underlying ideas since the 1990s, and the 2002 paper consolidated those ideas into a single coherent framework.
What are the four quadrants of the Stereotype Content Model?
The four quadrants are: high warmth + high competence, which produces admiration and is typically reserved for in-groups and close allies; high warmth + low competence, which produces pity and paternalistic prejudice and is associated in the original sample with elderly and disabled people; low warmth + high competence, which produces envy and resentment and is associated with high-status out-groups perceived as competitors; and low warmth + low competence, which produces contempt and disgust and is associated in the original sample with the homeless and other socially excluded groups.
What is the BIAS Map?
The BIAS Map (Behaviors from Intergroup Affect and Stereotypes) is the 2007 extension of the Stereotype Content Model, developed by Amy Cuddy, Susan Fiske and Peter Glick in the Journal of Personality and Social Psychology. It maps each of the four SCM quadrants onto specific behavioral tendencies. Warmth is associated with active behaviors (active facilitation when warmth is high, active harm when warmth is low). Competence is associated with passive behaviors (passive facilitation when competence is high, passive harm when competence is low). The BIAS Map is what turns SCM from a perception model into a behavior model.
Has the Stereotype Content Model been replicated?
Yes, and at scale. Cuddy, Fiske, Kwan, Glick, Demoulin and colleagues (2009) recovered the two-factor warmth-competence structure across eight European and three East Asian samples, with culturally specific variation rather than structural reversal — though collectivist samples did not place their reference groups in the high-high cell, which the U.S. samples did. Durante and colleagues (2017) then pooled 49 samples from 38 nations and found national inequality predicting more ambivalent, off-diagonal stereotype clusters. What is replicated is that the two dimensions organise group ratings and predict the four emotions. What is contested, in the data-driven work of Koch and colleagues (2016) and Nicolas, Bai and Fiske (2022), is whether warmth is a primary dimension — a dimension perceivers reach for unprompted — or something that emerges from a different underlying structure.
How does the Stereotype Content Model differ from Social Identity Theory?
Social Identity Theory, developed by Henri Tajfel and John Turner in 1979, claims that mere categorization into groups is sufficient to produce in-group favoritism, even when the categorization is arbitrary. The Stereotype Content Model claims that specific out-groups are perceived along warmth and competence dimensions and produce one of four distinct emotional reactions. The two are usually treated as complementary: SIT explains the always-on baseline of in-group preference, while SCM explains the differentiation across specific out-groups and which out-groups produce which emotions and behaviors.
What does the Stereotype Content Model say about brands?
Aaker, Vohs and Mogilner (2010) showed that consumer brands sort into the same four-quadrant structure as social groups: nonprofits cluster as warm but lower-competence, for-profits as competent but colder. Their key finding is the awkward one — perceived competence drove willingness to buy, so the warm sector’s quadrant placement cost it where it mattered. There is no published loyalty benchmark for admiration-quadrant brands, so treat claims of one with suspicion. The usable implication is that the two dimensions are separable but not fully independent: you have room to buff one without losing the other, and that room narrows the further out on either axis you already sit.
What is the compensation effect?
The compensation effect, documented in research by Nicolas Kervyn and colleagues, is the tendency for raters to push warmth and competence ratings in opposite directions when comparing two groups side by side, even when the underlying information would justify same-direction ratings. The mechanism appears to be a soft justice motive that wants to balance perceived virtue across groups. The compensation effect is a real problem for any application of the model that relies on within-subjects comparative ratings, including brand-tracking studies and political-candidate evaluations.
Is morality a separate dimension from warmth?
An influential research program led by Marco Brambilla and Colin Wayne Leach argues that warmth in the original Stereotype Content Model conflates two distinct sub-dimensions — sociability (how friendly and approachable a group is) and morality (how trustworthy and principled it is) — and that morality, not sociability, does the heavier work in stereotype formation and downstream behavior. The empirical pattern is consistent across more than a decade of papers: morality information is processed faster, weighted more heavily, and produces stronger behavioral effects than sociability information. The practical implication is that splitting warmth into sociability and morality gives you a sharper read in domains like brand trust and political messaging, because a brand can be friendly and still untrustworthy — and the friendliness will not save it.
How can the Stereotype Content Model be applied in product or game design?
Three specific moves drop out of the model. First, run a quadrant audit on your character lineup, brand portfolio, or NPC roster and look at the distribution; emotionally healthy designs cover all four quadrants in proportions matched to the genre. Second, use the BIAS Map to predict behavioral tendencies rather than only feelings — envy-quadrant entities are predicted to draw passive cooperation under stable conditions and hostility under stress, with the second half of that prediction the weaker one in the original data and carried by anger rather than envy directly. Third, treat warmth and competence as separable rather than as a single trade-off, while remembering they are not fully independent: the room to move on one axis without paying on the other shrinks the further out you already are.
References
- Fiske, S. T., Cuddy, A. J. C., Glick, P., & Xu, J. (2002). A model of (often mixed) stereotype content: Competence and warmth respectively follow from perceived status and competition. Journal of Personality and Social Psychology, 82(6), 878–902. doi:10.1037/0022-3514.82.6.878
- Cuddy, A. J. C., Fiske, S. T., & Glick, P. (2007). The BIAS map: Behaviors from intergroup affect and stereotypes. Journal of Personality and Social Psychology, 92(4), 631–648. doi:10.1037/0022-3514.92.4.631
- Cuddy, A. J. C., Fiske, S. T., Kwan, V. S. Y., Glick, P., Demoulin, S., Leyens, J.-P., et al. (2009). Stereotype content model across cultures: Towards universal similarities and some differences. British Journal of Social Psychology, 48(1), 1–33. doi:10.1348/014466608X314935
- Fiske, S. T., Cuddy, A. J. C., & Glick, P. (2007). Universal dimensions of social cognition: Warmth and competence. Trends in Cognitive Sciences, 11(2), 77–83.
- Asch, S. E. (1946). Forming impressions of personality. Journal of Abnormal and Social Psychology, 41(3), 258–290.
- Rosenberg, S., Nelson, C., & Vivekananthan, P. S. (1968). A multidimensional approach to the structure of personality impressions. Journal of Personality and Social Psychology, 9(4), 283–294.
- Wojciszke, B. (1994). Multiple meanings of behavior: Construing actions in terms of competence or morality. Journal of Personality and Social Psychology, 67(2), 222–232.
- Abele, A. E., & Wojciszke, B. (2007). Agency and communion from the perspective of self versus others. Journal of Personality and Social Psychology, 93(5), 751–763.
- Brambilla, M., Rusconi, P., Sacchi, S., & Cherubini, P. (2011). Looking for honesty: The primary role of morality (vs. sociability and competence) in information gathering. European Journal of Social Psychology, 41(2), 135–143.
- Leach, C. W., Ellemers, N., & Barreto, M. (2007). Group virtue: The importance of morality (vs. competence and sociability) in the positive evaluation of in-groups. Journal of Personality and Social Psychology, 93(2), 234–249.
- Aaker, J., Vohs, K. D., & Mogilner, C. (2010). Nonprofits are seen as warm and for-profits as competent: Firm stereotypes matter. Journal of Consumer Research, 37(2), 224–237. doi:10.1086/651566
- Eagly, A. H., & Karau, S. J. (2002). Role congruity theory of prejudice toward female leaders. Psychological Review, 109(3), 573–598.
- Cuddy, A. J. C., Fiske, S. T., & Glick, P. (2004). When professionals become mothers, warmth doesn’t cut the ice. Journal of Social Issues, 60(4), 701–718. doi:10.1111/j.0022-4537.2004.00381.x — note: this paper reports mothers losing perceived competence and gaining warmth, not competent women losing warmth.
- Harris, L. T., & Fiske, S. T. (2006). Dehumanizing the lowest of the low: Neuroimaging responses to extreme out-groups. Psychological Science, 17(10), 847–853. doi:10.1111/j.1467-9280.2006.01793.x
- Cikara, M., Botvinick, M. M., & Fiske, S. T. (2011). Us versus them: Social identity shapes neural responses to intergroup competition and harm. Psychological Science, 22(3), 306–313. doi:10.1177/0956797610397667 — note: a sports-rivalry fMRI study, not a stereotype-content study.
- Kervyn, N., Yzerbyt, V., & Judd, C. M. (2010). Compensation between warmth and competence: Antecedents and consequences of a negative relation between the two fundamental dimensions of social perception. European Review of Social Psychology, 21(1), 155–187.
- Fiske, S. T. (2011). Envy up, scorn down: How status divides us. Russell Sage Foundation.
- Kervyn, N., Yzerbyt, V. Y., Demoulin, S., & Judd, C. M. (2008). Competence and warmth in context: The compensatory nature of stereotypic views of national groups. European Journal of Social Psychology, 38(7), 1175–1183.
- Yzerbyt, V., Provost, V., & Corneille, O. (2005). Not competent but warm… really? Compensatory stereotypes in the French-speaking world. Group Processes & Intergroup Relations, 8(3), 291–308.
- Brambilla, M., & Leach, C. W. (2014). On the importance of being moral: The distinctive role of morality in social judgment. Social Cognition, 32(4), 397–408.
- Durante, F., Fiske, S. T., Gelfand, M. J., Crippa, F., Suttora, C., Stillwell, A., et al. (2017). Ambivalent stereotypes link to peace, conflict, and inequality across 38 nations. Proceedings of the National Academy of Sciences, 114(4), 669–674. doi:10.1073/pnas.1611874114
- Koch, A., Imhoff, R., Dotsch, R., Unkelbach, C., & Alves, H. (2016). The ABC of stereotypes about groups: Agency/socioeconomic success, conservative–progressive beliefs, and communion. Journal of Personality and Social Psychology. PubMed 27176773
- Imhoff, R., & Koch, A. (2017). How orthogonal are the Big Two of social perception? On the curvilinear relation between agency and communion. Perspectives on Psychological Science, 12(1), 122–137. doi:10.1177/1745691616657334
- Nicolas, G., Bai, X., & Fiske, S. T. (2022). A spontaneous stereotype content model: Taxonomy, properties, and prediction. Author copy (PDF)
- Cikara, M., & Fiske, S. T. (2011). Bounded empathy: Neural responses to outgroup targets’ (mis)fortunes. Journal of Cognitive Neuroscience. PMC3792561
- Cikara, M., & Fiske, S. T. (2013). Their pain, our pleasure: Stereotype content and schadenfreude. Annals of the New York Academy of Sciences, 1299(1), 52–59. doi:10.1111/nyas.12179
- Willis, J., & Todorov, A. (2006). First impressions: Making up your mind after a 100-ms exposure to a face. Psychological Science, 17(7), 592–598. doi:10.1111/j.1467-9280.2006.01750.x
- Oosterhof, N. N., & Todorov, A. (2008). The functional basis of face evaluation. Proceedings of the National Academy of Sciences, 105(32), 11087–11092. doi:10.1073/pnas.0805664105
- Jones, B. C., DeBruine, L. M., Flake, J. K., et al. (2021). To which world regions does the valence–dominance model of social perception apply? Nature Human Behaviour, 5, 159–169. doi:10.1038/s41562-020-01007-2
- Sherif, M., Harvey, O. J., White, B. J., Hood, W. R., & Sherif, C. W. (1961). Intergroup conflict and cooperation: The Robbers Cave experiment. University of Oklahoma Book Exchange.
- Tajfel, H., & Turner, J. C. (1979). An integrative theory of intergroup conflict. In W. G. Austin & S. Worchel (Eds.), The social psychology of intergroup relations (pp. 33–47). Brooks/Cole.
Related Reading
- Social Identity Theory: An S-Tier Behavioral Designer’s Guide
- Realistic Conflict Theory: An S-Tier Behavioral Designer’s Guide
- Stereotype Threat: An S-Tier Behavioral Designer’s Guide
- Moral Foundations Theory: An S-Tier Behavioral Designer’s Guide
- The Halo Effect: An S-Tier Behavioral Designer’s Guide
- The Octalysis Framework